Finest - Fast, Cheap, Good. Pick Three
Overview
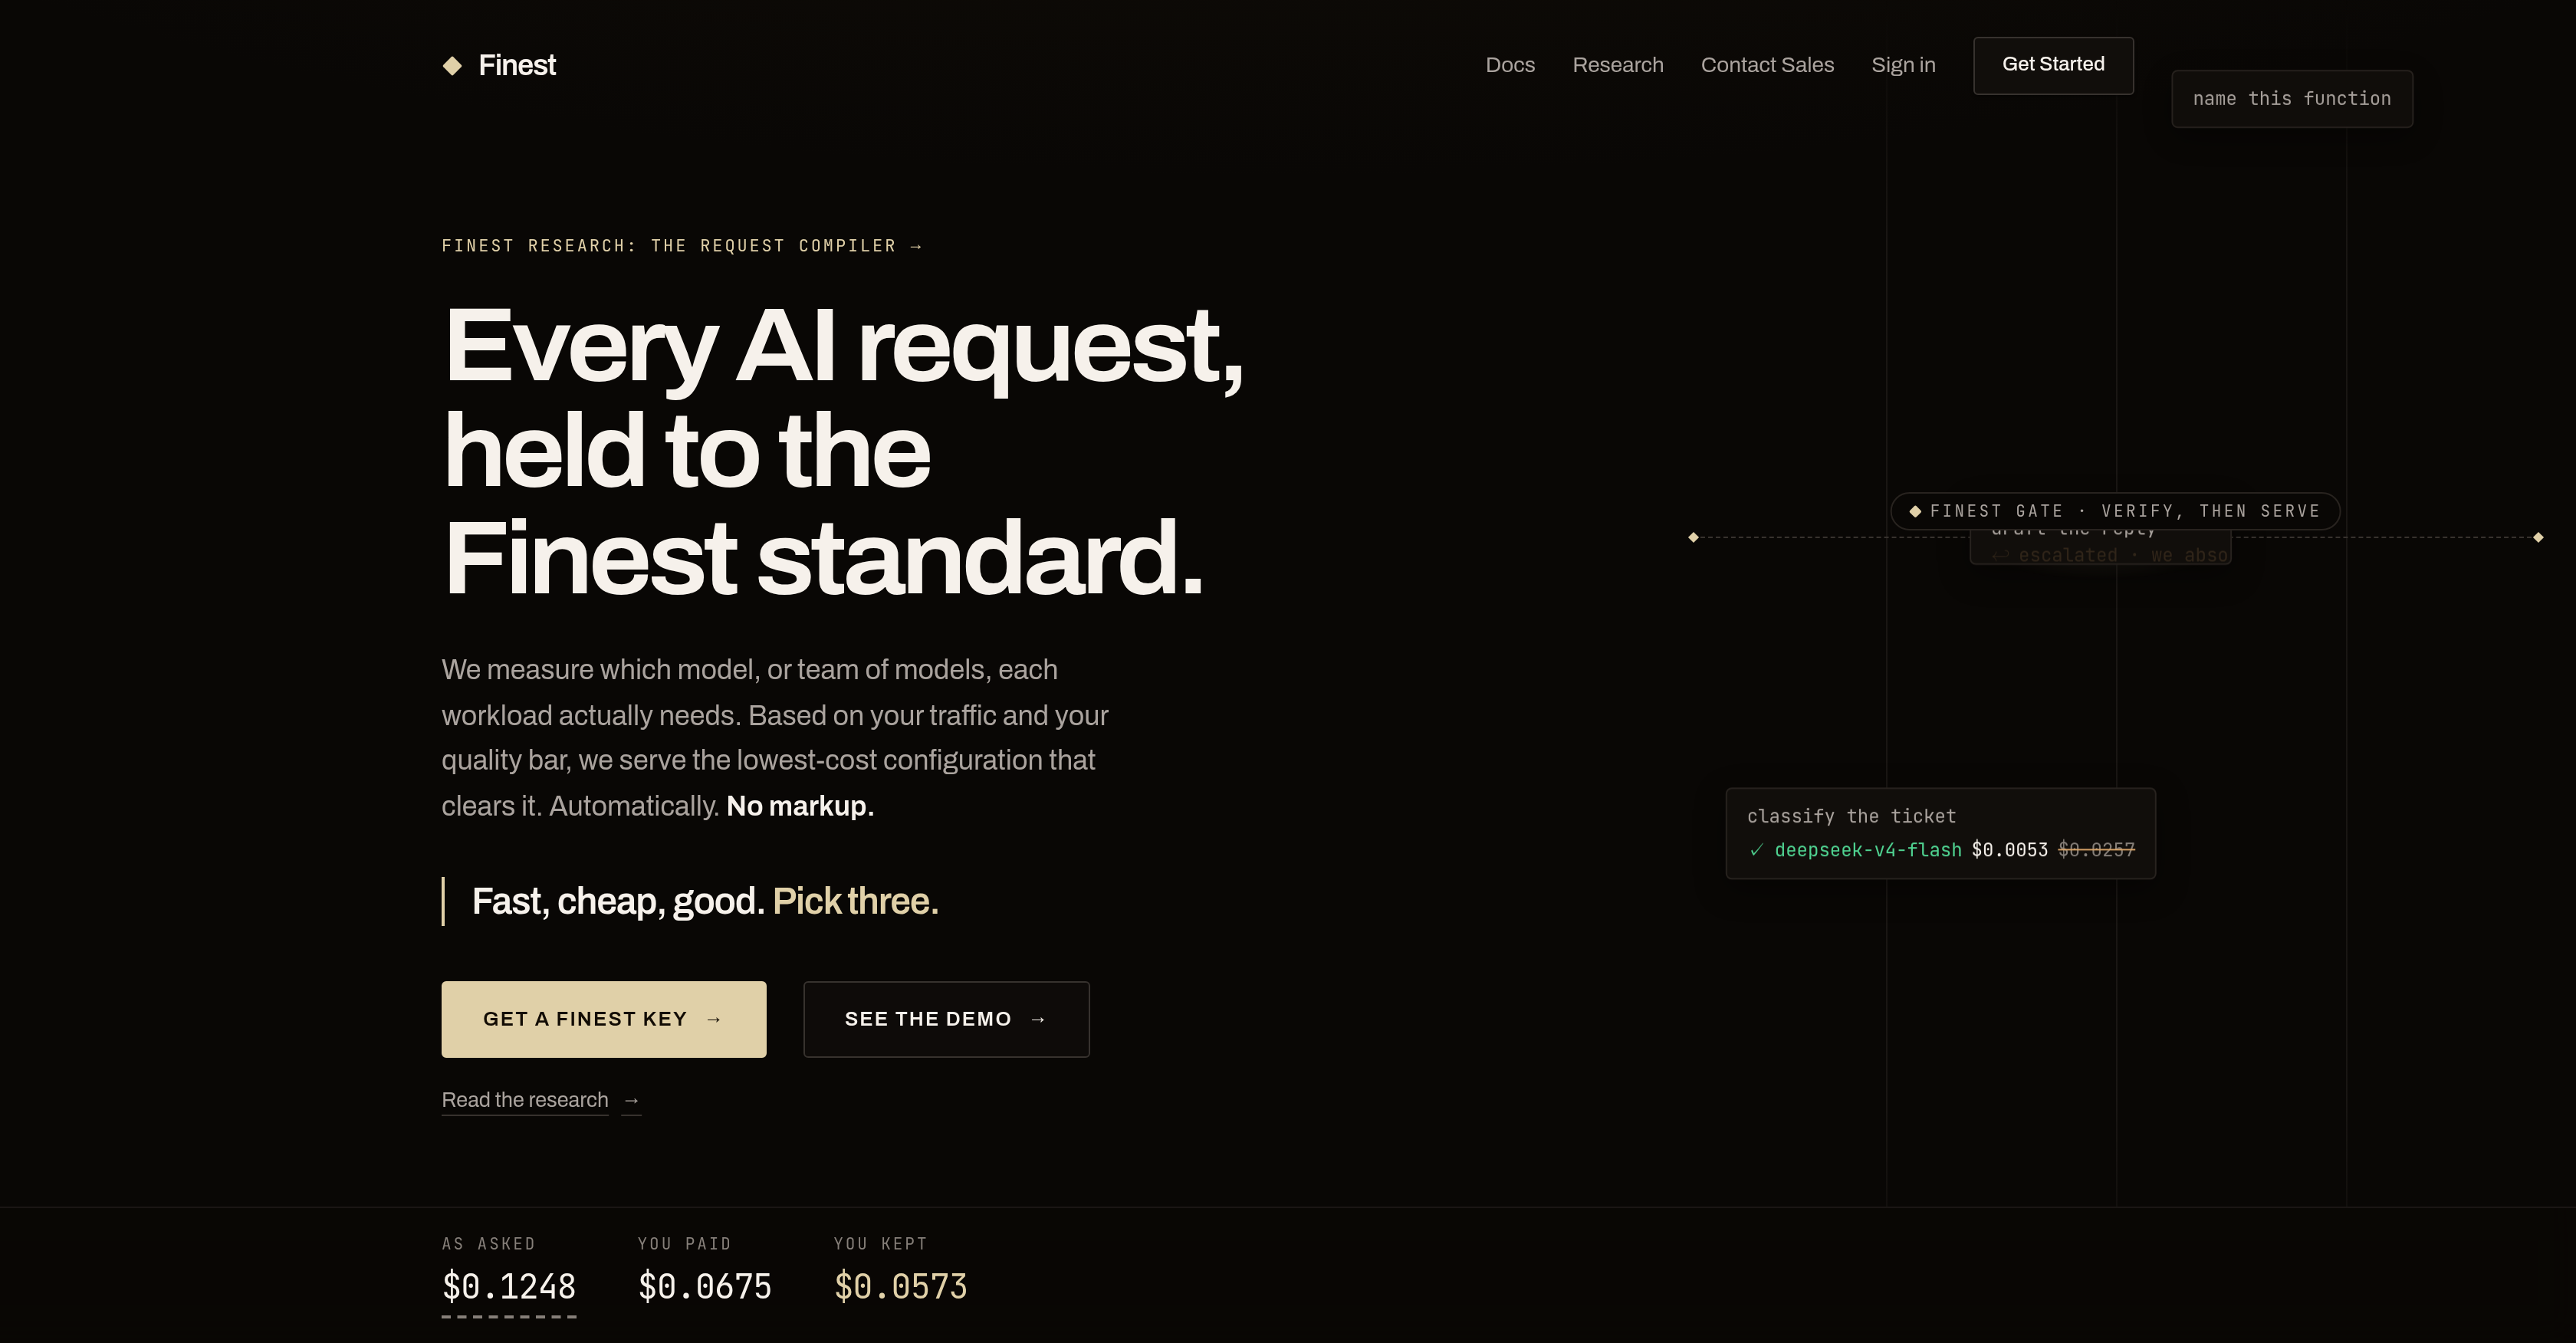
- Slash your AI API expenses automatically with a system that routes every request to the lowest-cost model configuration that clears your quality bar
- Get faster AI responses by splitting complex requests into parallel segments answered by the cheapest capable models
- Maintain high-quality outputs while cutting costs through continuous verification that reassesses every route whenever a new model is released
- Keep full visibility into incremental AI spend with precise per-request pricing and cost transparency for every call
- Eliminate budget waste by capping output per route and sending non-critical requests to smaller, cheaper models, charging escalation costs back to savings
- Optimize workload distribution across models with load balancing that manages varying requirements while minimizing API costs
- Start saving immediately with zero prior experience—sign up, get a Finest key, and let the system handle all AI workflow optimization automatically
- Pay nothing unless you save with the 'No savings, no fee' policy that aligns Finest's earnings directly with your API cost reduction
Pros & Cons
Pros
- Sophisticated analysis system
- Determines most cost-efficient model
- Regularly measures and compares models
- Switches models on solid evidence
- Provides precise pricing per request
- Maintains transparency and control over costs
- Balances speed, affordability, and quality
- Allows meeting all parameters concurrently
- Caps output per route
- Splits requests into pieces for parallel processing
- Optimizes routes and conserves resources
- Divides complex calls into cost-effective segments
- Uses expensive models only when necessary
- Continuous verification mechanism
- Reassesses every route for new model releases
- Constantly provides best possible configurations
- Reduces API expenses
- Commits to value-oriented service
- Operates on 'No savings, no fee' policy
- Controls budget
- Optimizes route
- Assures Quality
- Reduces API cost
- Provides Advanced analytics
- Manages Resource
- Provides Load Balancing
- Measures Performance
- Compares Model
- Serves lowest-cost configuration automatically
- No markup on configurations
- Provides detailed information on request
- Breaks sequence in manageable tasks
- Ability to re-verify every route
- Updates system with every model release
- Free if no savings
- Provider pricing, no markup
- Proof-based charge system
- Thorough workload analysis
- Personalized customer support
- Maintains security
- Continuously attempts API cost reduction
- Emergent Status Terms tracking
- One analytics cookie policy
Cons
- No mobile version
Reviews
Rate this tool
Loading reviews...
❓ Frequently Asked Questions
Finest achieves cost-effectiveness in AI workflows by utilizing a sophisticated analysis system to determine the most cost-efficient model for each job based on specific workload requirements. The system measures and compares varying models and configurations, switching only when solid evidence indicates a different model can perform an equivalent or better job at a reduced cost.
The essential features of Finest include AI workflow optimization, cost-effectiveness, quality assurance, advanced analytics, cost transparency, resource management, load balancing, performance measurement, model comparison, AI operations, budget control, route optimization, continuous verification, and API cost reduction. It is designed to provide a value-oriented service to their clients.
Yes, Finest can optimize routes and conserve resources. It has the ability to cap output per route and split requests into pieces that are answered in parallel. This functionality results in optimized routes and ensures resource conservation.
The 'No savings, no fee' policy of Finest is a part of its commitment towards providing a value-oriented service to their clients. It essentially means that if Finest is unable to save money for the user in the AI operation costs, the user does not have to pay a fee for using the service.
Pricing in Finest is highly transparent. The system provides users with precise pricing on each request, maintaining control and transparency over the incremental costs associated with AI operations.
Yes, Finest uses advanced analytics in its operation. It has a sophisticated analysis system that continually measures and compares various models and configurations based on workload requirements to determine the most cost-efficient model.
Finest is highly effective in capping output per route. This ensures even complex calls are divided into more cost-effective segments, ensuring the more expensive models are used only when highly necessary.
'Fast, cheap, good. Pick three' in relation to Finest communicates the service's ability to provide speedy, affordable, and high-quality AI operations concurrently. This phrase indicates that users no longer have to trade off one for another but can have all three simultaneously.
Yes, Finest has a continuous verification mechanism in place that reassesses every route whenever a new model is released. This ensures the system stays updated with any model changes, always providing the best possible configuration to meet the user's quality and cost-effectiveness requirements.
Finest manages API cost reduction by employing a number of tactics, including serving the lowest-cost configuration that meets the required standards automatically, splitting requests into pieces to be answered in parallel, and by sending requests that don't require the large model to smaller, cheaper models - charging the cost of escalation back to the savings.
Yes, Finest ensures quality assurance while reducing API expenses. By verifying each route every time a new model is released and serving only the most cost-efficient model for each job, it maintains high-quality outputs while minimizing costs.
Yes, Finest can split requests into more cost-effective segments. It can cap output per route and split requests into pieces that are answered in parallel, thus reducing costs and maximizing efficiency.
Load balancing in Finest plays a vital role in managing workload requirements across varying models and configurations to ensure optimal performance while minimizing costs.
Finest compares models to ensure cost-effectiveness through its sophisticated analysis system. It constantly measures and compares various models and configurations based on workload requirements to choose the cheapest model that can perform the same or better job.
Yes, Finest reassesses routes every time a new model is released as part of its continuous verification mechanism. This ensures Finest's system always provides the best possible configuration to meet user requirements.
Finest helps in lowering API expenses without sacrificing quality by applying optimization techniques such as capping output per route, splitting requests to be answered in parallel, and continuously verifying every route every time a new model is released. It also serves the lowest-cost configuration that fulfills the quality standards.
No prior experience is required to use Finest. It is designed to automatically handle all aspects of AI workflow optimization, load balancing, performance measurement, route optimization, cost management, and more while keeping the user fully informed.
To start using Finest, simply sign up and get a Finest key. It offers a free trial for those who are interested in testing the service before committing to a fee.
Finest ensures optimal performance measurement by continuously comparing and measuring various models and configurations against the workload requirements. This kind of real-time comparison allows it to always serve the most cost-efficient and effective configuration.
Yes, Finest offers a value-oriented service to clients. Its fundamental commitment is to reduce their API expenses without sacrificing quality. Its 'No savings, no fee' policy further emphasizes this commitment.
Pricing
Pricing model
Free
Paid options from
Free