
Overview
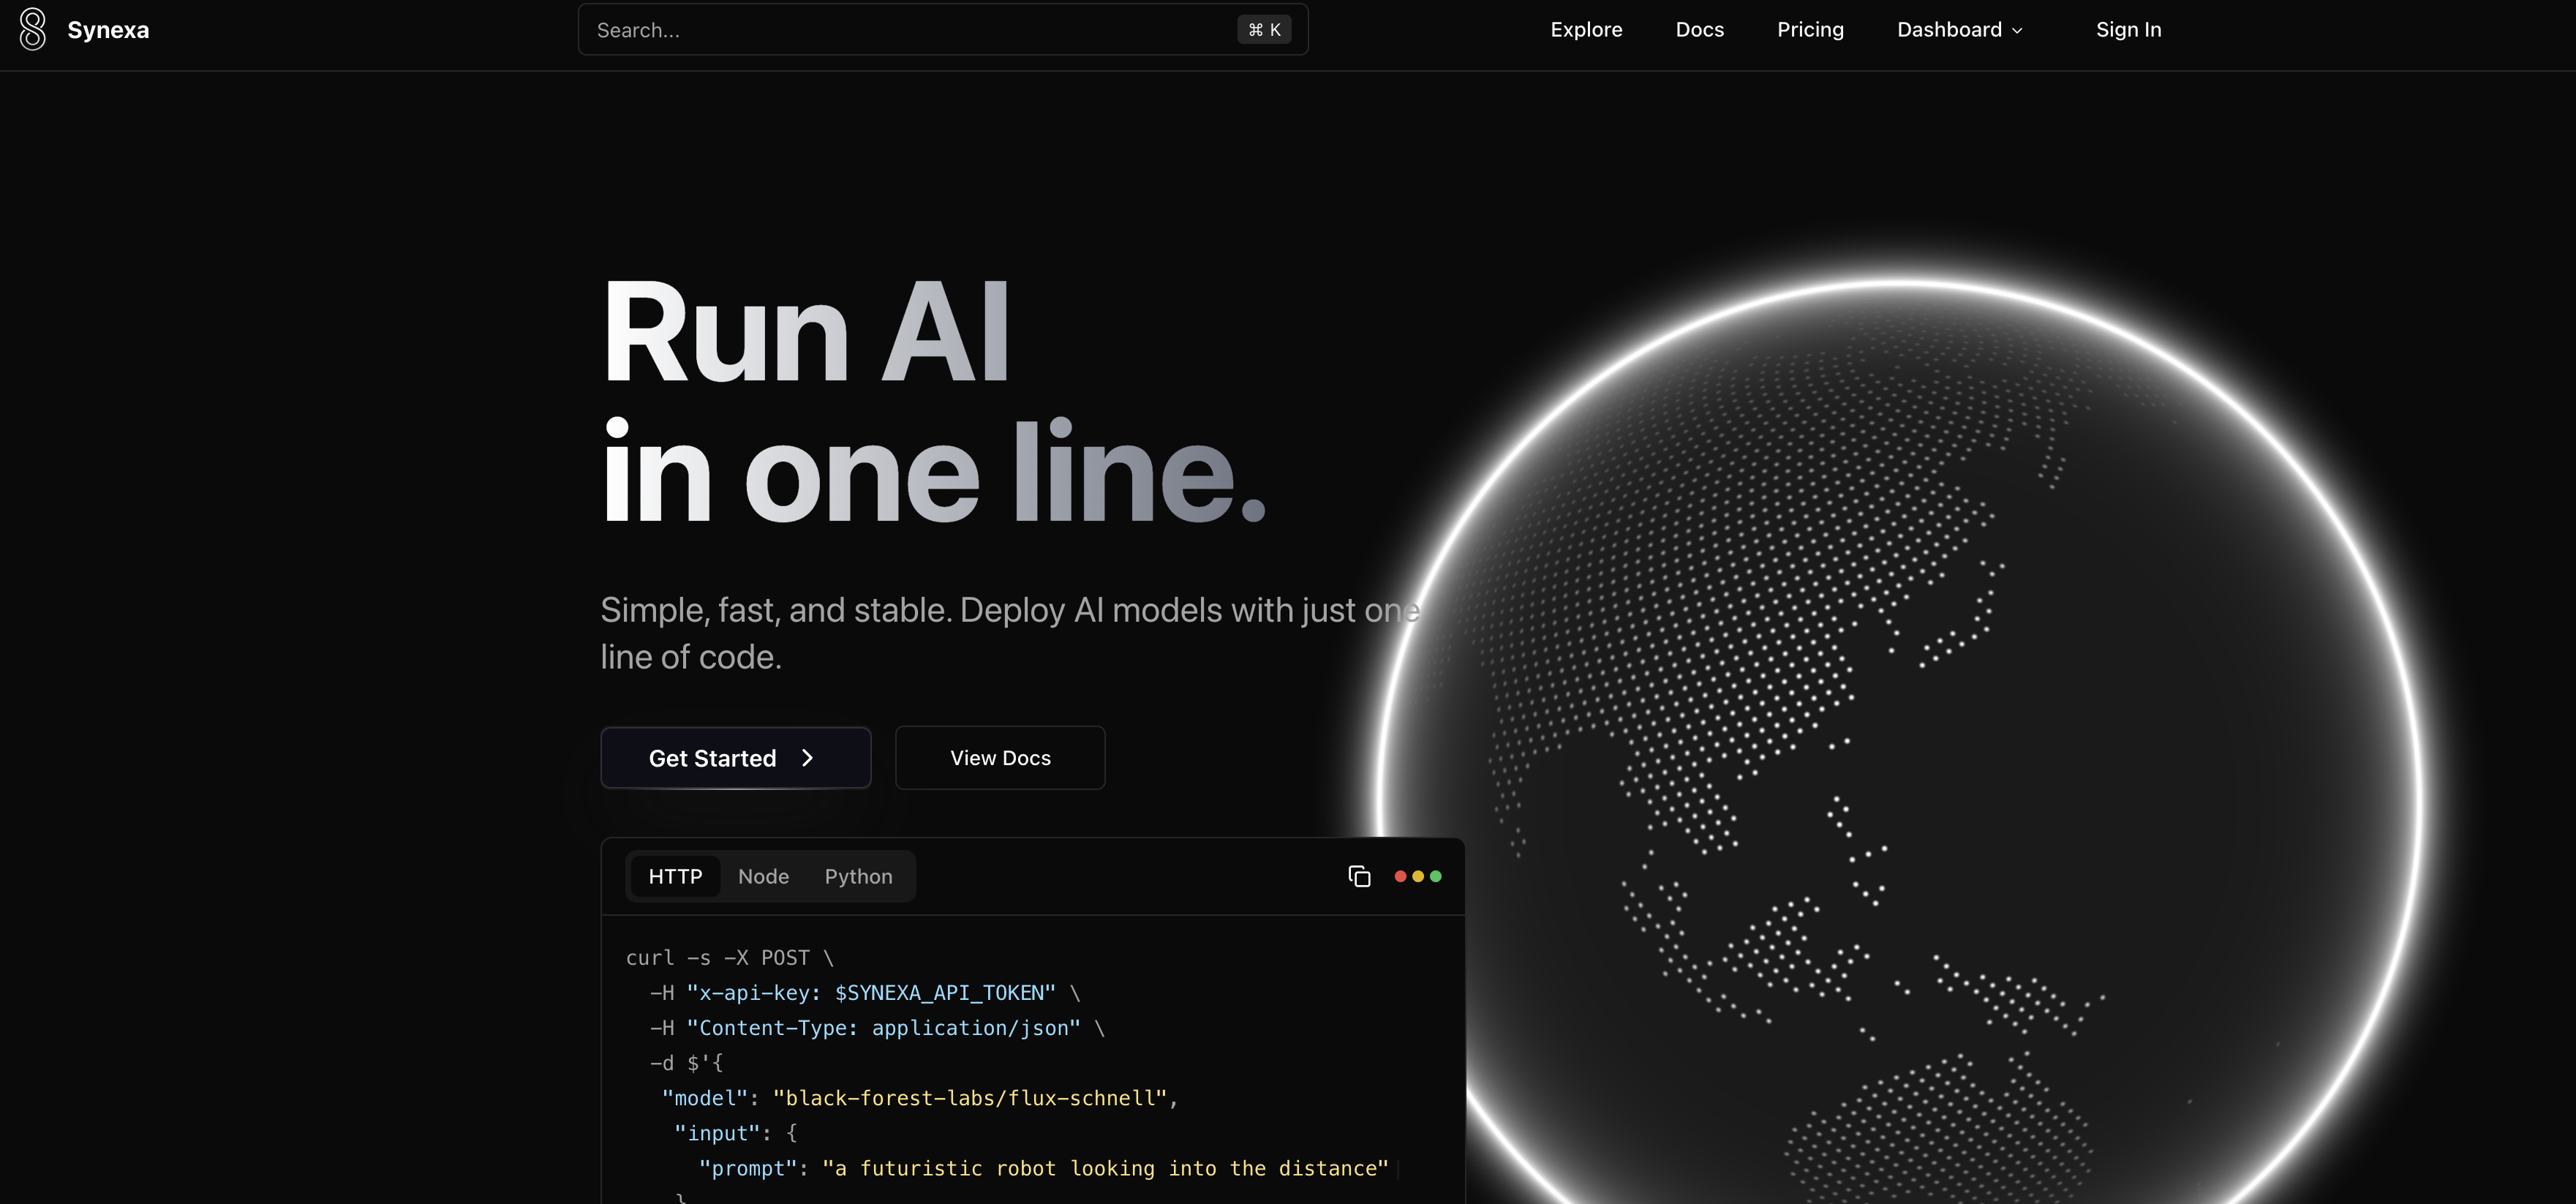
- Launch AI models instantly with just one line of code using streamlined deployment that eliminates complex setup
- Generate high-resolution images from text and convert images to video with advanced diffusion models optimized for sub-second performance
- Scale automatically during traffic spikes with serverless infrastructure that bills only for compute used, scaling to zero when idle
- Reduce AI compute costs by up to 62% with economical A100 GPU pricing and pay-per-use serverless API models
- Access ready-to-use AI models from a growing gallery including image restoration, video manipulation, and speech generation
- Integrate seamlessly with Python, JavaScript, and REST API through comprehensive SDKs and developer documentation
- Ensure reliable global performance with enterprise-grade GPUs across three continents delivering sub-100ms latency and 99.9% uptime
Pros & Cons
Pros
- Generates images and videos
- Image restoration capabilities
- Image captioning feature
- Model fine-tuning functionality
- Generates speech
- Video content manipulation
- High-resolution text to image
- Advanced image to video conversion
- Includes Controlnets and Loras
- Automatic scaling feature
- Python, JavaScript, REST API support
- Enterprise-grade GPU units
- Optimized latency and uptime
- Frequently updated model gallery
- Performance-optimized inference engine
- Improved performance on diffusion models
- Smart routing system
- 99.9% uptime guarantee
- Ongoing additions to model gallery
- Ultra-high-resolution imaging
- Blazing Fast Inference Engine
- Traffic spikes response
- Easy development integration
- Sub- 100ms latency
- Image to video transformation
Cons
- Limited language support
- Dependent on GPU units
- Serverless-only functionality
- Overemphasis on image/video tasks
- Lack of customizability
- No support for other APIs
- Potentially high latency across continents
- No local deployment option
- Only ready-to-use models
- No free version
Reviews
Rate this tool
Loading reviews...
❓ Frequently Asked Questions
Synexa is an AI tool designed for the deployment of artificial intelligence models. It offers a streamlined process allowing AI models to be operationalized with only one line of code. Synexa provides extensive functionalities including generating images and videos, restoring images, captioning images, model fine-tuning, and speech generation. It also supports conversion of image to video and high-resolution text to image generation.
Synexa has a variety of operational capabilities such as generating images and videos, restoring images, and captioning images. It is also adept in fine-tuning models and generating speech. Synexa's unique offering includes transformation and manipulation of video content, high-resolution text to image generation, and advanced conversion of image to video.
Synexa enables deployment of AI models with a remarkable simplicity. The streamlined coding approach requires only one line of code for AI models to be operationalized. This simplicity reduces the barrier of entry for individuals seeking to rapidly implement and make use of AI models.
The advanced conversion of image to video in Synexa signifies its ability to effectively utilize AI in a unique way. This functionality creates an avenue to generate dynamic content from static images, broadening the potential uses and applications of the AI models within Synexa.
Synexa offers comprehensive developer support for Python and JavaScript through its SDKs and API documentation. This allows for seamless integration of AI services within applications developed in these languages.
Synexa has an auto-scaling system that instantaneously handles traffic spikes. This infrastructure ensures users are billed solely for what they utilize. When idle, resources scale to zero, but they can scale unlimitedly when traffic demand increases.
The serverless AI API models in Synexa reduce the need for server management, as the AI workloads operate within Synexa's infrastructure. This principle fosters a more efficient and cost-effective AI implementation, as users only pay for the compute resources they use and don't need to manage their own server infrastructure.
Synexa's enterprise-grade GPU units are integral to its performance. They enhance processing speed and reduce latency for better user experience. These GPU units are located across three continents to optimize latency and ensure 99.9% uptime.
The version of Synexa with Controlnets and Loras is intended for development purposes. With these features, developers have more advanced tools that can aid in the creation and optimization of AI models within Synexa.
Yes, there is a model gallery in Synexa. The gallery includes a substantial collection of ready-for-use AI models. Synexa regularly adds new models to its gallery, so users can leverage a wide variety of AI tools for their needs.
Synexa offers comprehensive capabilities for image and video generation. It can generate images and videos, restore images, and perform advanced conversion of image to video. Additionally, it supports high-resolution text to image generation, which can be utilized for several applications.
Synexa provides comprehensive support for the REST API. This is delivered through extensive SDKs and API documentation. It allows developers to easily integrate Synexa's AI capabilities into their applications through the REST API.
Synexa optimizes its latency and uptime through a performance-oriented infrastructure. The platform utilizes enterprise-grade GPU units that are located across three continents. This global coverage ensures sub-100ms latency and guarantees a 99.9% system uptime, providing reliable and swift services.
Synexa's serverless AI API models make it a cost-effective option for running AI applications. Users only pay for the compute resources used, thereby saving on infrastructural costs. Synexa also offers the most economical A100 GPU pricing, which can result in savings of up to 62% compared to other providers.
Synexa facilitates a variety of AI models, offering wide operational capabilities. It provides functions for generating images and videos, restoring images, captioning images, and model fine-tuning. Synexa also supports the generation of speech, high-resolution text to image generation, and conversion of image to video.
The performance of Synexa's inference engine is optimized for enhanced diffusion model performance. Specifically, Synexa's optimized inference engine is able to deliver up to 4x faster performance on diffusion models, ensuring users experience sub-second generation times with popular models.
Synexa supports high-resolution text to image generation. This feature allows conversion of text input into corresponding high-definition images. The capability can be utilized in a broad range of applications, from content creation to technical visualizations.
Synexa provides developmental integration support through SDKs and comprehensive API documentation. It caters to popular programming languages used by developers including Python and JavaScript, as well as the more general REST API.
The uniqueness of Synexa's model fine-tuning process lies in its simplicity and efficiency. AI models can be fine-tuned using a one-line coding approach which drastically simplifies the complexity of traditional fine-tuning processes.
Synexa's speech generation functionality is utilized to transform text into speech. This can be leveraged in the development of voice assistants, audio content generation, and numerous applications where speech output is necessary.
Pricing
Pricing model
Free Trial
Paid options from
$0.00/unit
Billing frequency
Pay-as-you-go